September 15, 2026
Why Salesforce Data Cleanup Projects Always Become Prevention Projects
Nobody sets out to buy a data quality platform. They buy a merge tool because two Salesforce orgs just collided in a merger. They buy an import tool because a migration cutover is three weeks out. They buy something, anything, because a specific, dated problem forced the decision.
We looked across a range of Cloudingo customer accounts spanning different industries, deal sizes, and buying reasons, and one pattern held every time: the project that starts as “clean this up” doesn’t stay that way. It becomes a prevention project, and it happens on a predictable timeline, not a random one.
Here’s what that pattern looks like, and what it means if you’re the one running the cleanup right now.
The trigger is always narrow
Across every account we looked at, the reason someone finally picks up a dedupe tool traces back to one of four things:
A merger or acquisition. Two Salesforce orgs need to become one, and every account, contact, and opportunity record just doubled its odds of having a duplicate somewhere.
A system migration. A team is moving off a legacy tool, an old dedupe product, a CRM system, a manual process, and the cutover date is forcing the data question that’s been ignored for years.
A live, regenerating integration. An ERP sync, a Marketo instance, a routing tool, a data enrichment feed. Something is writing new records into Salesforce on its own schedule, and every cleanup pass is stale again within weeks.
Manual pain crossing a threshold. A workflow that used to be tolerable, outreach lists checked by hand, VLOOKUPs run before every board meeting, a homegrown script someone built years ago, finally takes too long or breaks too often to keep doing it that way.
None of these are data quality problems on their face. They’re merger problems, migration problems, integration problems, and capacity problems that happen to surface through the data. That’s worth sitting with, because it explains something that trips up a lot of admins evaluating tools: the trigger tells you almost nothing about how big the actual fix needs to be.
What you buy vs. what you actually need
Whatever the trigger, the mental model at purchase is almost always smaller than the problem. “A merge tool.” “A one-time cleanup.” “An import automation tool.” “A DemandTools replacement.” Nobody walks in asking for infrastructure. They ask for a fix to the thing that’s on fire right now.
This isn’t a sign the buyer under-scoped the project or that sales oversold the wrong package. It’s consistent enough, across accounts with nothing else in common, that it looks less like a mistake and more like how these projects are supposed to start. A CTO evaluating tools after a merger isn’t thinking about ongoing prevention rules. They’re thinking about getting two orgs merged without losing data. A RevOps lead three weeks from a migration cutover isn’t thinking about long-term data governance. They’re thinking about the cutover.
That narrow framing does real work early on. It makes the decision small enough to make quickly, and it gets the tool in the door before the bigger problem, the one that caused the trigger in the first place, has to be named out loud.
But it also means the tool usually gets evaluated, purchased, and onboarded against a much smaller job than the one it’s capable of doing. Tools like Import Wizard exist from day one, but they’re rarely what anyone was shopping for. They’re discovered later, not sold up front.
That gap, between the narrow reason someone bought and the actual size of the problem underneath it, is exactly where the next shift happens.
The pivot: why cleanup becomes prevention
At some point, the language changes. “How do we clean up what’s here” becomes “how do we stop bad data from getting in.” That shift is the hinge of the whole pattern, and it tends to happen for one of three reasons.
- Someone shows the admin a capability they didn’t know to ask for. This is the most common trigger, and the most controllable one. A walkthrough surfaces automated prevention rules, dashboards, or alert-based monitoring that were sitting in the product the whole time, unused because nobody had scoped for them at purchase.
- A personnel change brings in someone with a bigger mandate. A new admin, a new RevOps lead, a new director inherits the tool and looks at it with fresh eyes. Not “what was this bought to fix” but “what could this actually be doing for us.”
- An internal event forces the issue. A second merger. Another migration. A new integration going live. The same kind of trigger that started the project in the first place shows up again, except this time the team already has the tool, so the conversation skips straight to “how do we make sure this doesn’t happen again.”
How fast this shift happens varies. Sometimes it’s within the first working session, sometimes it’s closer to a year. But the direction doesn’t vary. Once a team sees what ongoing prevention looks like, going back to “clean it up when it gets bad again” stops being an option anyone chooses on purpose.
What this means if you’re mid-cleanup right now
If your duplicates are coming from a live, regenerating source, an ERP sync, a Marketo instance, a routing tool, this pattern applies to you differently than it does to a one-time merger cleanup. A live integration doesn’t produce a backlog you clear once. It produces a leak. Cleanup alone was never going to hold, because the source keeps writing new duplicates in on its own schedule, independent of anything your team does.
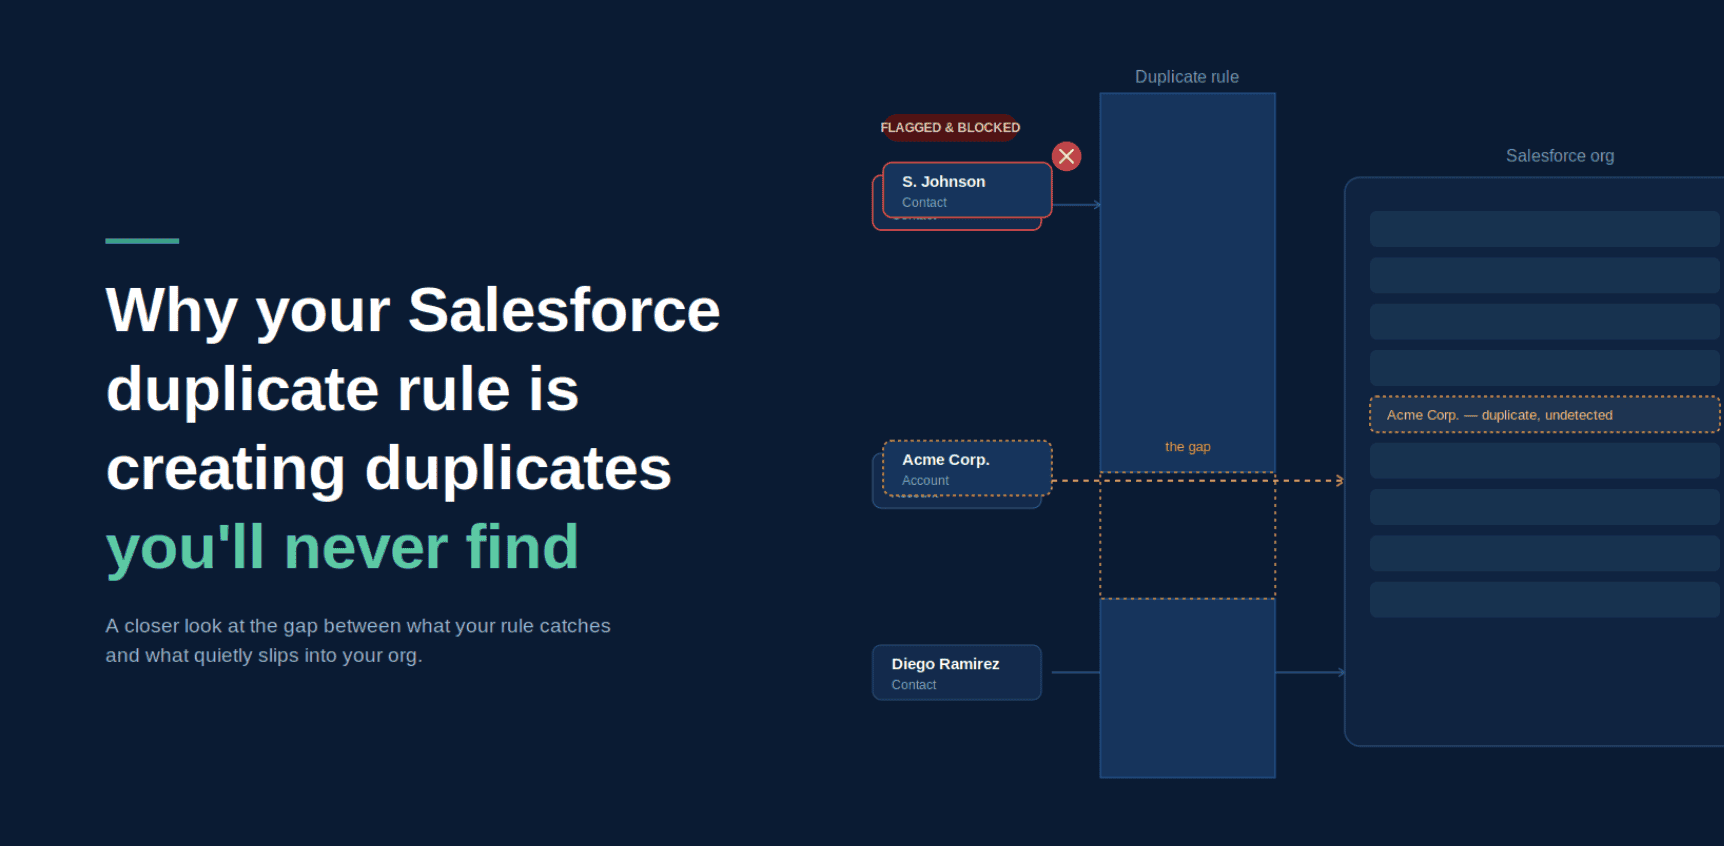
That distinction matters beyond convenience. Duplicate and inconsistent records don’t just clutter a database. They skew forecasting, misroute leads, break attribution, and quietly erode trust in whatever reporting sits downstream. Increasingly, that downstream also includes AI-driven scoring, segmentation, and automation, which are only as reliable as the records feeding them. A model built on duplicated, inconsistent data doesn’t produce bad output because the model is wrong. It produces bad output because the input was never clean to begin with.
None of this means every cleanup project needs to become a platform overnight. It means the honest question to ask, partway through a cleanup, isn’t “are we done yet.” It’s “will this stay done.” If the answer is no, that’s not a sign the project failed. It’s the same pattern showing up on schedule.
The goal was never clean data once
Every account in this pattern started the same way: a narrow trigger, a narrow purchase, and a pivot that happened whether or not anyone planned for it. That’s not a flaw in how these projects get sold or scoped. It’s just how the problem tends to reveal its real size.
If you’re running a cleanup right now and it’s starting to feel like it won’t stay finished, that’s worth paying attention to. The goal was never data that’s clean once. It’s data that stays clean without someone doing it by hand every quarter.